The Naive Bayes Probabilistic Model
Abstractly, the probability model for a classifier is a conditional model.
over a dependent class variable with a small number of outcomes or classes, conditional on several feature variables through . The problem is that if the number of features is large or when a feature can take on a large number of values, then basing such a model on probability tables is infeasible. We therefore reformulate the model to make it more tractable.
Using Bayes' theorem, we write
In plain English the above equation can be written as
In practice we are only interested in the numerator of that fraction, since the denominator does not depend on and the values of the features are given, so that the denominator is effectively constant. The numerator is equivalent to the joint probability model
which can be rewritten as follows, using the chain rule for repeated applications of the definition of conditional probability:
Now the "naive" conditional independence assumptions come into play: assume that each feature is conditionally independent of every other feature for given the class . This means that
for, and so the joint model can be expressed as
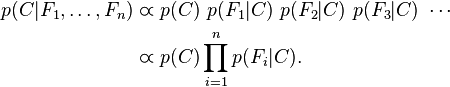
This means that under the above independence assumptions, the conditional distribution over the class variable can be expressed like this:
where (the evidence) is a scaling factor dependent only on, i.e., a constant if the values of the feature variables are known.
Models of this form are much more manageable, since they factor into a so-called class prior and independent probability distributions . If there are classes and if a model for each can be expressed in terms of parameters, then the corresponding naive Bayes model has (k − 1) + n r k parameters. In practice, often (binary classification) and (Bernoulli variables as features) are common, and so the total number of parameters of the naive Bayes model is, where is the number of binary features used for classification and prediction.
Read more about this topic: Naive Bayes Classifier
Famous quotes containing the words naive and/or model:
“The naive notion that a mother naturally acquires the complex skills of childrearing simply because she has given birth now seems as absurd to me as enrolling in a nine-month class in composition and imagining that at the end of the course you are now prepared to begin writing War and Peace.”
—Mary Kay Blakely (20th century)
“... if we look around us in social life and note down who are the faithful wives, the most patient and careful mothers, the most exemplary housekeepers, the model sisters, the wisest philanthropists, and the women of the most social influence, we will have to admit that most frequently they are women of cultivated minds, without which even warm hearts and good intentions are but partial influences.”
—Mrs. H. O. Ward (1824–1899)